




How to clean a customer list in Excel
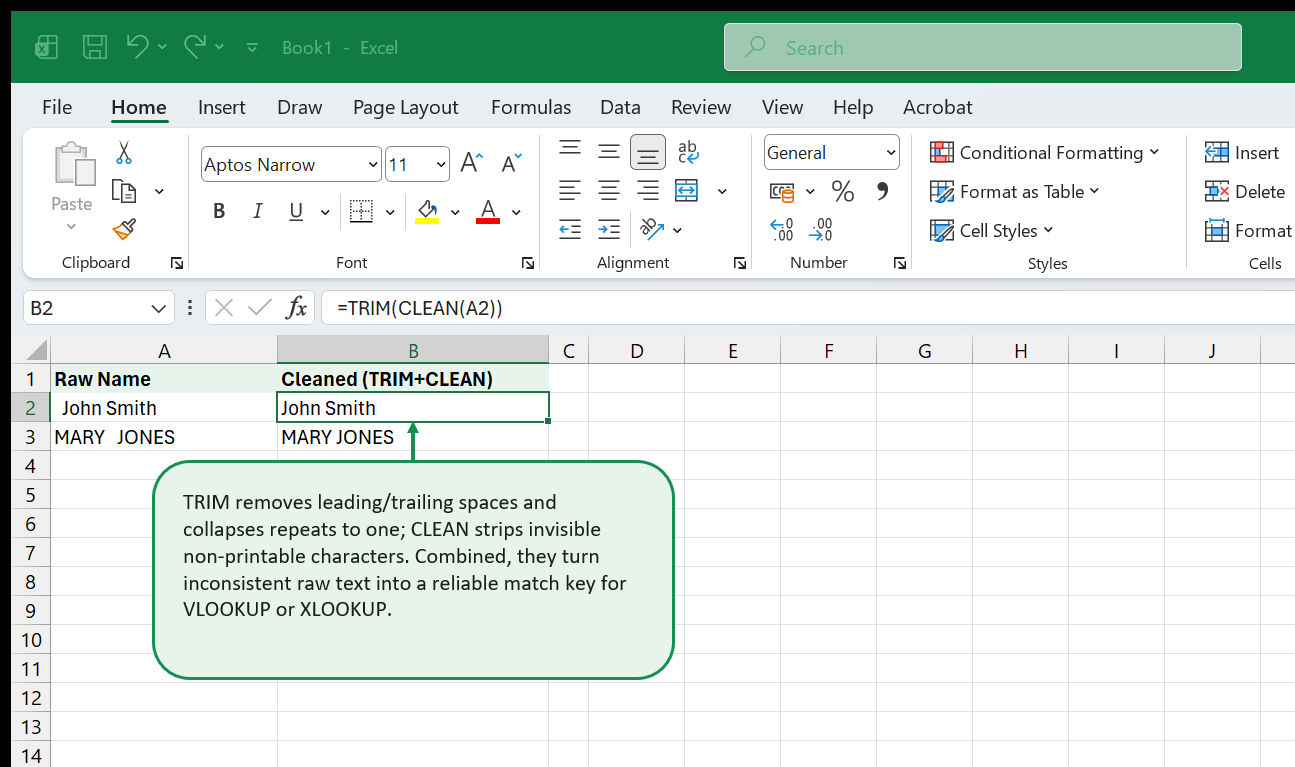
Stripping trailing whitespace and non-breaking web spaces (CHAR 160) from imported CRM customer names before deduplicating.
Watch alongside this article
Public YouTube resources matched to this article's topic, functions, and practice goal.
Cleaning Data in Excel: Microsoft Excel Crash Course
Simon Sez IT
Open on YouTube (opens in a new tab)
How to Clean Data in Excel in 10 Minutes (Free File)
MyOnlineTrainingHub
Open on YouTube (opens in a new tab)
Customer lists look simple until you try to use one — for a mail merge, a CRM
import, a lookup formula, or a report by region. Then the 4,000-row file turns
out to contain the same company three times under slightly different names, 60
rows with a trailing space in the email, and a country column with UK, U.K.,
United Kingdom, and GB in it.
The goal is not a neat-looking list. It is a list that produces the same answer every time you ask it a question.
Work on a copy, always
Three sheets before anything else:
Raw— the untouched export. Never edited. Ever.Clean— where the work happens.Checks— the validation formulas from the end of this article.
This is not caution for its own sake. Half of data cleaning is discovering, two
hours in, that a transformation was wrong — and the only way to recover is to
compare against the original. A cleaning pass without a Raw sheet is a
one-way door.
If the source is a CSV, import it through Data → From Text/CSV rather than double-clicking it. Double-clicking strips leading zeros from customer IDs and guesses date formats by your machine’s locale rather than the file’s. The specifics are in cleaning a bank statement export, and they apply to any CSV.
Strip the invisible characters first
Run this before anything else, because every subsequent comparison depends on it:
=TRIM(CLEAN([@Customer]))TRIM removes leading, trailing, and repeated internal spaces. CLEAN removes
non-printing control characters, which arrive constantly from older systems and
from anything that has passed through a PDF.
One thing neither catches: the non-breaking space (character 160), which is
what you get from data copied out of a web page. It looks exactly like a space
and is not one. If TRIM appears to do nothing on a value that clearly has a
trailing space, this is why:
=TRIM(CLEAN(SUBSTITUTE([@Customer],CHAR(160)," ")))Make that your standard text-cleanup formula and use it on every text column.
Normalise the fields that will be matched on
Decide which column is the key — the one that identifies a customer uniquely. Customer ID if the export has one; email otherwise. Then normalise it hard, because every later step compares on it.
Email:
=LOWER(TRIM([@Email]))Email addresses are case-insensitive in practice, so Jane@Acme.com and
jane@acme.com are the same person and must become the same string.
Then check they are plausible addresses:
=IF(AND(ISNUMBER(FIND("@",[@EmailClean])),ISNUMBER(FIND(".",TEXTAFTER([@EmailClean],"@")))),"","Check email")That tests for an @ and a dot after it. It is not full validation — nothing in
Excel is — but it catches the empty cells, the n/a, and the phone number
somebody typed into the wrong column.
Company name: strip the legal suffix into its own column so matching works on the distinctive part:
=TRIM(SUBSTITUTE(SUBSTITUTE(SUBSTITUTE([@NameClean]," Ltd","")," Limited","")," Inc",""))Country: map it rather than correcting it by hand. Put a two-column lookup on
a Lists sheet (UK → United Kingdom, U.K. → United Kingdom, GB → United Kingdom) and use XLOOKUP with a flag for anything unmapped:
=XLOOKUP([@Country],MapFrom,MapTo,"UNMAPPED")Filter for UNMAPPED and you have the list of variants nobody has decided about
yet. That beats scrolling, and it repeats next month.
Phone numbers: decide a single format and convert to it. The important part is to store them as text, not numbers — a phone number stored as a number loses its leading zero and may appear in scientific notation.
Only split names if you have to
Splitting Jane Smith into first and last is easy. Splitting Dr. Maria van der Berg III correctly is not, and every formula-based approach gets some portion
of a real list wrong — multi-word surnames, single-name entries, reversed
Smith, Jane order, titles, suffixes.
So: only split if the destination system genuinely requires separate fields. If it does, use Data → Text to Columns or Power Query’s Column From Examples, then check the tail of the list, where the unusual names sort to. Keep the original full name column either way.
Find the near-duplicates
Exact de-duplication is the easy part —
3 ways to remove duplicates covers Remove
Duplicates, UNIQUE, and Power Query. Run that on the normalised key column.
The harder problem is the duplicates that are not byte-identical. Acme Ltd and
Acme Limited. Jon Smith and John Smith. These will not be caught by any
exact comparison, and in a customer list they are the expensive ones, because
they split a customer’s history in two.
Two practical approaches:
Match on a reduced key. Build a column that is lowercase, with spaces,
punctuation, and legal suffixes removed, then COUNTIF on that:
=COUNTIF(tblCust[MatchKey],[@MatchKey])Acme Ltd and ACME Limited. both reduce to acme, and the count flags them.
Match on the email domain. Two records sharing @acme.com are very likely
the same organisation even when the company names differ:
=TEXTAFTER([@EmailClean],"@")Sort by that column and the related records sit together. (On older Excel,
=MID(A2,FIND("@",A2)+1,255) does the same.)
Review the flagged pairs by eye. This step does not automate well, and attempting to automate it is how two different companies get merged into one.
Handle blanks deliberately
Filter every important column for blanks and decide what each one means. An empty
Country is not the same thing as Unknown — one is missing data you might be
able to recover, the other is a stated fact.
For a required field, flag rather than guess:
=IF([@EmailClean]="","Missing email","")Then count the flags on the Checks sheet so the scale of the problem is a
number rather than an impression.
Validate before you hand it over
Put these on the Checks sheet with the expected value beside each:
=ROWS(tblClean)=SUMPRODUCT(--(COUNTIF(tblClean[Key],tblClean[Key])>1))=COUNTBLANK(tblClean[EmailClean])=COUNTIF(tblClean[Country],"UNMAPPED")Row count (compare to Raw minus intentional deletions — a count that dropped
further than you expected means a filter was applied before a copy), remaining
duplicates, missing required fields, unmapped categories.
A clean list is boring: every count that should be zero is zero, and the row count ties. That is how you know it is ready.
Make it repeatable if it will recur
Everything above can be done once with formulas. If the same export arrives every month, build it in Power Query instead — the steps are recorded, and next month is a Refresh rather than an afternoon. Power Query vs Excel formulas covers where that line sits, and the messy data cleanup practice file has the trailing spaces, mixed case, and near-duplicate names already in it if you want to work through the sequence first.
FREE EXCEL UPDATES
Get practical Excel tips in your inbox
New tutorials, tools, templates, and worked examples a few times a month. Unsubscribe anytime.
Go deeper with this skill
Turn messy imported data into a reliable table that formulas, pivots, and reports can use safely. For this article, the goal is to practice: Turn a messy customer export into something you can safely import — backup discipline, TRIM and CLEAN, name and email normalisation, finding near-duplicates that exact matching misses, and the validation pass before handover.
Practice workbook setup
Copy messy sample data to a raw-data sheet and keep the original untouched while you clean a separate working copy.
Practice workflow
- Identify the expected columns and data types before changing anything.
- Remove obvious blanks and duplicates, then check whether any removals need business approval.
- Standardize spacing, casing, dates, and number formats.
- Create a small before-and-after table so the cleanup can be reviewed.
Quality checks
- The row count before and after cleanup is explainable.
- Key columns have no unexpected blanks.
- Dates, IDs, and amounts are stored as the correct data type.
Common mistakes
- Cleaning directly over the only copy of the data.
- Removing duplicates without deciding which columns define a duplicate.
- Fixing visible rows while hidden filtered rows stay messy.
Next actions
- Convert the cleaned range into an Excel Table.
- Repeat the same cleanup with Power Query if the data will arrive again.
Formula focus: test TRIM(), CLEAN(), PROPER(), LOWER(), SUBSTITUTE(), COUNTIF(), TEXTBEFORE(), FIND() with normal rows, blank inputs, and at least one edge case.
