




Power Query refresh checklist
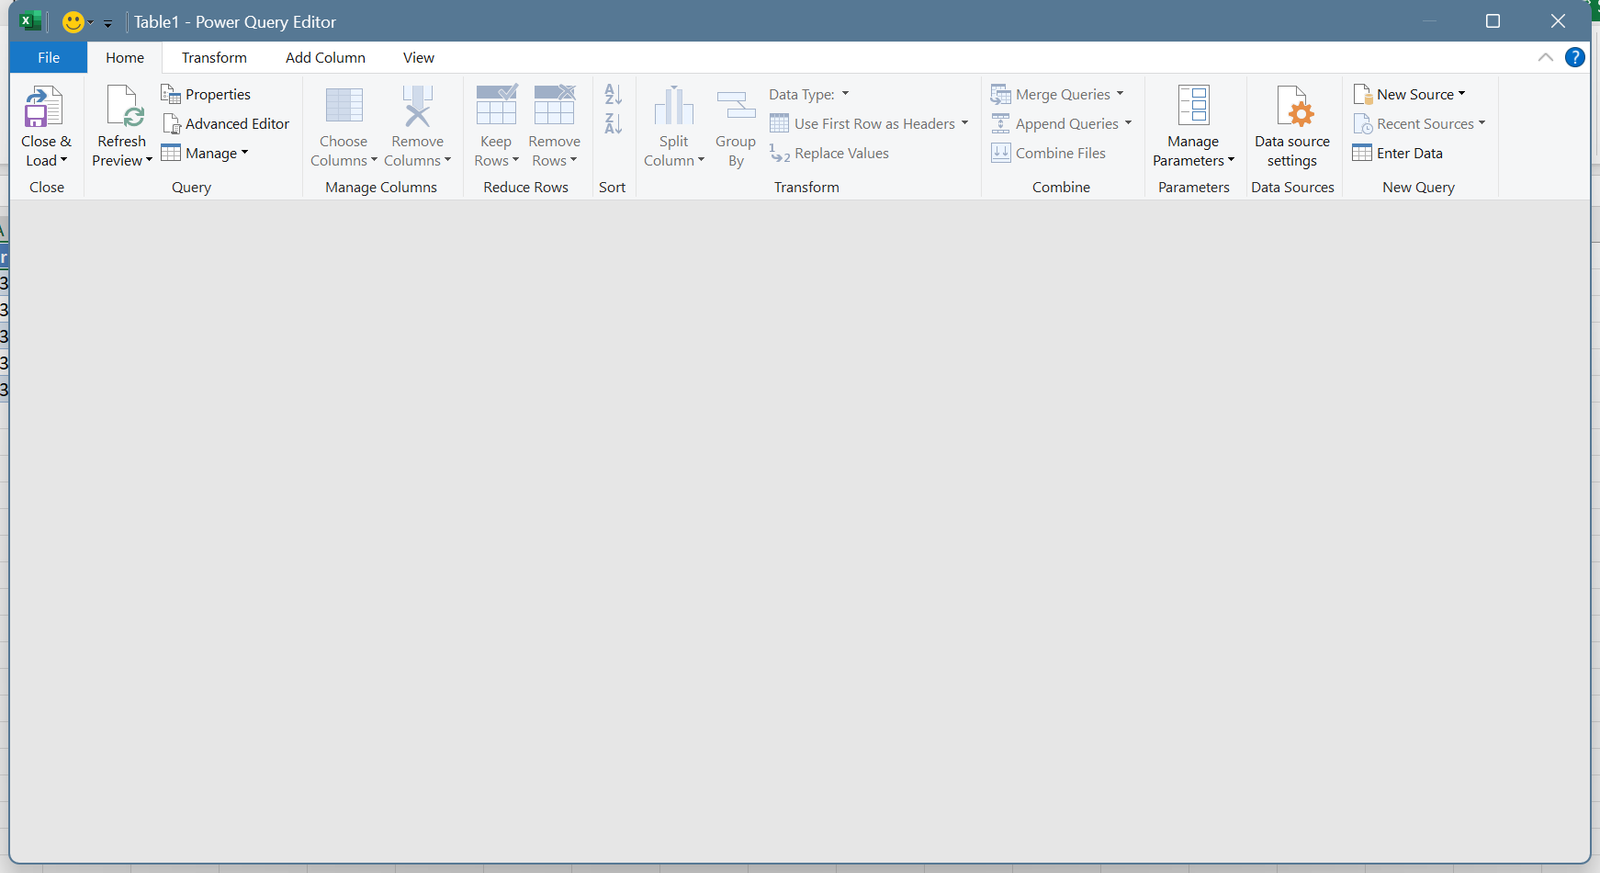
Auditing Applied Steps, column data types, and file path parameters so weekly Power Query refreshes never break.
Watch alongside this article
Public YouTube resources matched to this article's topic, functions, and practice goal.

Powerful trick to combine all Excel files in a folder AUTOMATICALLY
Chandoo
Open on YouTube (opens in a new tab)
Excel Power Query Course: Power Query Tutorial for Beginners
Simon Sez IT
Open on YouTube (opens in a new tab)
Master Data Cleaning Essentials with Power Query And Excel
Simon Sez IT
Open on YouTube (opens in a new tab)Power Query is powerful because it repeats cleanup steps exactly. That is also the risk: a change in the source file gets processed with the same confidence as a correct one, and the output still looks like a finished table. Nothing goes red. The totals are just wrong.
This is the checklist worth running when a query feeds anything that other people read — before the refresh, and again after it.
Before: confirm the source is what the query expects
Open Data → Queries & Connections, hover a query, and read the source line in the preview. Then check four things about the file it names:
- The path still exists. Queries store an absolute path. A file moved from a
local folder into SharePoint, or a drive remapped from
G:toH:, breaks the query — loudly, which is the good case. - The sheet or table name is unchanged. If the query points at
Sheet1and someone renamed itData, the refresh fails. If it points at a named table, it survives the sheet rename, which is one more reason to source from tables rather than sheets wherever you can. - New files follow the same layout. For a folder-based query combining monthly exports, one file with an extra header row at the top will be processed as though that row were data.
- No required column has been renamed. This is the one that bites hardest, and it gets its own section below.
The Changed Type trap
Almost every query Power Query records for you ends up with an automatic Changed Type step, and that step hard-codes column names.
Rename Amount to Amount (USD) in the source, and the refresh throws:
Expression.Error: The column 'Amount' of the table wasn't found.That is the friendly failure. The unfriendly one is a source that adds a column: the automatic step doesn’t know about it, so the new column arrives untyped and lands in your output as text — including, often, a numeric column that then silently stops summing.
Two defences, in order of preference:
- Delete the automatic Changed Type that sits immediately after the source step, and set types explicitly at the end of the query instead, on the columns you actually use. Types applied at the end are applied to the shape you built, not the shape the source happened to have that day.
- If you keep it, read it. Click the step and look at the formula bar. It lists every column by name. That list is your contract with the source file.
Either way, resist the habit of clicking through the Applied Steps list without looking. The steps are code; they deserve the same reading as a formula.
Check data types, not just the header row
Dates, amounts, percentages, and IDs all import badly in their own ways:
- Dates imported as text won’t group by month or year downstream — the same
failure covered in
cleaning data before a pivot table.
Watch the locale: a
DMYsource read asMDYconverts 03/04 to the wrong day without error for every date where both parts are 12 or under. - IDs with leading zeros become numbers and lose the zeros. Set those columns to Text explicitly, early, before anything else touches them.
- Amounts with currency symbols or thousands separators arrive as text. Strip them in the query rather than in the sheet afterwards, so the fix repeats.
- Whole numbers vs decimal. Picking Whole Number on a column that later receives 10.5 produces an error row, not a rounded value.
After: look for error rows
A refreshed query can succeed overall and still contain errors in individual
cells. Power Query shows a “N errors” link at the top of the preview; in the
loaded table, errors appear as Error values.
Find them deliberately rather than by eye: in the query editor, right-click the suspect column and choose Keep Errors to see only the broken rows. Diagnose there, then undo that step.
Common causes, in rough order of frequency: unexpected blanks where a type conversion expected a value, text in a numeric column, a new category value that the query’s conditional logic has no branch for, and a date that doesn’t exist in the chosen locale.
Decide what should happen to errors — removed, replaced with null, or flagged — and make that an explicit step. Errors that are silently dropped by Remove Errors are rows that have left your dataset without telling anyone.
Validate the row count and the totals
This is the check that catches the failures nothing else catches. After a refresh, compare two numbers against the source system:
=ROWS(tblQueryOutput)=SUM(tblQueryOutput[Amount])A refresh is only useful if the result still matches reality. The row count catches filters that are now excluding more than they used to, a folder query that missed a file, or an inner join that quietly dropped unmatched rows. The sum catches type problems — a column half-imported as text sums low and keeps a straight face.
Keep both of these in cells on a Checks sheet with the expected value beside
them, not in your head. A control total nobody wrote down is not a control.
Watch the join step specifically
If the query merges two sources, the join kind decides what happens to rows that don’t match. Inner silently drops them. Left Outer keeps them with nulls, which is usually what you want, because it makes the mismatch visible.
After a merge, expand the joined column and count the nulls. A count that jumps from 3 to 300 between refreshes means a key changed format somewhere upstream — often exactly the leading-zero or trailing-space problem from the type section above.
Keep the query readable for whoever refreshes it next
Rename your Applied Steps to say what they do — Removed internal accounts
rather than Filtered Rows1. Future you, debugging a refresh at month-end, is
reading that list under time pressure.
And if the query is doing cleanup that the source system could do properly instead, note that somewhere. Power Query is excellent at absorbing a messy export; it is not a reason to keep the export messy.
If you are setting up your first query rather than maintaining one, start with getting started with Power Query, and Power Query vs Excel formulas covers which jobs belong in the query at all.
FREE EXCEL UPDATES
Get practical Excel tips in your inbox
New tutorials, tools, templates, and worked examples a few times a month. Unsubscribe anytime.
Go deeper with this skill
Create a repeatable cleanup and refresh process instead of doing the same manual edits every month. For this article, the goal is to practice: What to check before and after a Power Query refresh — source paths, renamed columns, the Changed Type trap, error rows, and the row-count tie-out that catches silent data loss.
Practice workbook setup
Use a raw export with extra columns, inconsistent text, blanks, or repeated monthly files.
Practice workflow
- Import the data into Power Query and rename every meaningful step.
- Remove columns only after confirming they are not needed downstream.
- Set data types deliberately for dates, numbers, IDs, and text.
- Load the cleaned result to a table and refresh it after changing the source.
Quality checks
- Applied steps are named clearly enough to review later.
- Data types are correct before loading the result.
- Refresh works without manual cleanup in the worksheet.
Common mistakes
- Editing the loaded table instead of the query steps.
- Removing columns before checking whether reports depend on them.
- Ignoring errors caused by new values or changed source headers.
Next actions
- Create a small refresh checklist and keep it beside the report.
- Try combining two files or appending a new month to test repeatability.
Formula focus: even if this workflow is not formula-heavy, add one check cell that confirms the final output still matches the source data.
